
How to Connect Your Database to ChatGPT (4 Ways Compared)
TL;DR: ChatGPT cannot open a database connection by itself. You give it one through a custom MCP server (added at chatgpt.com/plugins), a GPT Action that calls your own middleware API, or your own app built on the OpenAI API. Whatever the route, connect with a read-only database role and put a gateway between ChatGPT and production.
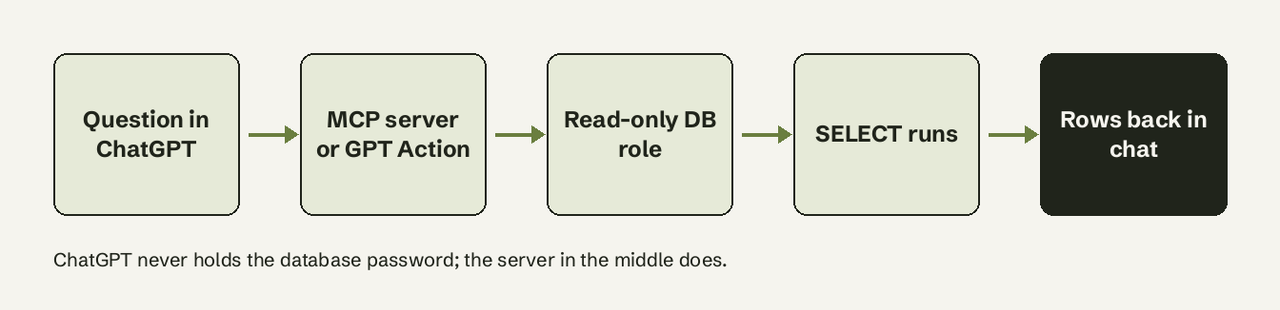
To connect ChatGPT to a SQL database today, run (or use) an MCP server that can read your schema and run read-only queries, expose it over HTTPS at a /mcp endpoint or through OpenAI's Secure MCP Tunnel, then add it in ChatGPT under Plugins > "Add custom MCP server". This works for PostgreSQL, MySQL, SQL Server and data warehouses such as BigQuery or Snowflake, because the MCP server, not ChatGPT, holds the driver and the credentials. The older routes still work: paste your schema and copy SQL by hand, or build a Custom GPT whose Action calls a middleware API, which is what OpenAI's own GPT Action SQL cookbook describes. ChatGPT plugins in the 2023 sense are gone; "plugin" now means a packaged MCP server plus skills.
Why People Want to Talk to Their Database
The appeal is obvious. SQL is expressive but demanding. Even experienced engineers forget column names or look up JOIN syntax for the third time this month. For product managers, sales and ops, SQL is a wall between them and numbers they need daily.
Natural language promises to cut through that: ask "how many users signed up last week from Germany?" and get an answer, without a query editor or a ticket for an engineer. The real question is how to wire ChatGPT to live data without handing a general-purpose assistant the keys to production.
What you need before you connect anything
- A database reachable from the server you'll run (PostgreSQL 12+, MySQL 8, SQL Server, or a warehouse).
- A ChatGPT plan that allows custom MCP servers or Custom GPTs. Plan rules change often; vendor docs in October 2026 describe Plus and Pro accounts enabling developer mode for read/fetch-style custom servers, Business, Enterprise and Edu workspaces needing an admin to allow them, and Free having none. Check your Settings before you build.
- A read-only database role. Create it first, whatever route you choose:
-- PostgreSQL: a role ChatGPT's connector can use
CREATE ROLE chatgpt_ro WITH LOGIN PASSWORD 'use-a-long-random-password';
GRANT CONNECT ON DATABASE app TO chatgpt_ro;
GRANT USAGE ON SCHEMA public TO chatgpt_ro;
GRANT SELECT ON ALL TABLES IN SCHEMA public TO chatgpt_ro;
ALTER DEFAULT PRIVILEGES IN SCHEMA public GRANT SELECT ON TABLES TO chatgpt_ro;
ALTER ROLE chatgpt_ro SET statement_timeout = '15s';
-- MySQL 8 equivalent
CREATE USER 'chatgpt_ro'@'%' IDENTIFIED BY 'use-a-long-random-password';
GRANT SELECT ON app.* TO 'chatgpt_ro'@'%';-- SQL Server: read-only user in one database
CREATE LOGIN chatgpt_ro WITH PASSWORD = 'use-a-long-random-password';
USE app;
CREATE USER chatgpt_ro FOR LOGIN chatgpt_ro;
ALTER ROLE db_datareader ADD MEMBER chatgpt_ro;Option 1: Paste Your Schema Into ChatGPT and Ask It to Write SQL
This is where most people start. Copy your table definitions into a conversation, describe what you want, and ask for the query.
-- Paste this schema into ChatGPT:
CREATE TABLE users (
  id SERIAL PRIMARY KEY,
  email TEXT NOT NULL,
  country TEXT,
  created_at TIMESTAMP DEFAULT NOW(),
  plan TEXT
);

CREATE TABLE subscriptions (
  id SERIAL PRIMARY KEY,
  user_id INTEGER REFERENCES users(id),
  started_at TIMESTAMP,
  cancelled_at TIMESTAMP,
  mrr NUMERIC
);
Then ask: "Write a PostgreSQL query to show MRR by country for users who signed up in the last 90 days." You paste the answer into your database client, run it and check the results.
What works: it's fast for one-off queries and needs no setup, no connector and no plan upgrade. It's also the safest option: ChatGPT never touches the database.
What breaks down:
- You copy SQL and results back and forth by hand.
- The schema isn't remembered unless you use a Project or Custom GPT instructions.
- ChatGPT doesn't see your data distribution, so it can write valid SQL that returns nonsense (wrong status values, soft-deleted rows counted).
- Non-technical teammates still can't use it on their own, and nothing is logged.
Option 2: Build a Custom GPT with Database Access (GPT Actions)
A Custom GPT can call an external REST API through an Action. Because managed databases don't expose a query API, OpenAI's cookbook puts a middleware app in between: it accepts a query over REST, forwards it to the database, converts the result (CSV in their example) and returns it.
User -> Custom GPT -> Action (OpenAPI 3.1) -> your middleware -> database (read-only role)The cookbook names two middleware designs: one endpoint that accepts any SQL the GPT writes (easy, flexible, riskier), or a set of endpoints for specific allowed queries (more control, fewer model errors), for which it suggests PostgREST or Hasura. A minimal version of the first design, with the guardrails the cookbook leaves to you:
import os
import re
import psycopg2
from fastapi import FastAPI, Header, HTTPException

app = FastAPI()
READ_ONLY = re.compile(r"^\s*(select|with)\b", re.IGNORECASE)

@app.post("/query")
def run_query(payload: dict, x_api_key: str = Header(...)):
    if x_api_key != os.environ["ACTION_API_KEY"]:
        raise HTTPException(401, "bad key")
    sql = payload.get("q", "")
    if not READ_ONLY.match(sql) or ";" in sql.strip().rstrip(";"):
        raise HTTPException(400, "only one SELECT or WITH statement allowed")
    # connect as the read-only role, never as the owner
    with psycopg2.connect(os.environ["READONLY_DATABASE_URL"]) as conn:
        with conn.cursor() as cur:
            cur.execute("SET LOCAL statement_timeout = '15s'")
            cur.execute(sql)
            rows = cur.fetchmany(1000)
            columns = [d[0] for d in cur.description]
    return {"columns": columns, "rows": rows}
The regex is a convenience, not security: the read-only role and the timeout are what actually protect you.
What works: a real chat interface over live data, and ChatGPT can pass results to its code interpreter for charts or regressions.
What breaks down: you build and host the middleware, write the OpenAPI schema, and handle auth. It lives only inside ChatGPT, and there are no dashboards, saved queries, schedules or alerts.
Option 3: Use the OpenAI API Directly to Build NL-to-SQL
Instead of ChatGPT as the interface, the OpenAI API becomes the engine inside your own app: your app takes a question, sends it with the schema to a model, gets SQL back, runs it and shows results. The Responses API can also call an MCP server directly with the mcp tool type, using server_url for a remote server or tunnel_id for a private one, with require_approval controlling whether each tool call needs a human OK (MCP guide).
import os
import psycopg2
from openai import OpenAI

client = OpenAI()
SCHEMA = """
users(id, email, country, created_at, plan)
subscriptions(id, user_id, started_at, cancelled_at, mrr)
"""

def question_to_sql(question: str) -> str:
    resp = client.responses.create(
        model=os.environ.get("OPENAI_MODEL", "gpt-5"),
        instructions=f"Write one PostgreSQL SELECT for this schema. Return SQL only.\n{SCHEMA}",
        input=question,
    )
    return resp.output_text.strip()

def run(sql: str):
    with psycopg2.connect(os.environ["READONLY_DATABASE_URL"]) as conn:
        with conn.cursor() as cur:
            cur.execute(sql)
            return [d[0] for d in cur.description], cur.fetchmany(1000)

columns, rows = run(question_to_sql("Top 10 countries by MRR this month"))
What works: complete control over UI, permissions, history and model choice.
What breaks down: you now maintain a production NL-to-SQL system. Schema context gets hard past a few dozen tables, ambiguous questions need clarification flows, and you still have to build the UI, dashboards, alerting and access control. See [why text-to-SQL breaks between demo and production](/blog/text-to-sql-performance-cliff-demo-fails-production/).
Option 4: Add a Database MCP Server to ChatGPT (step by step)
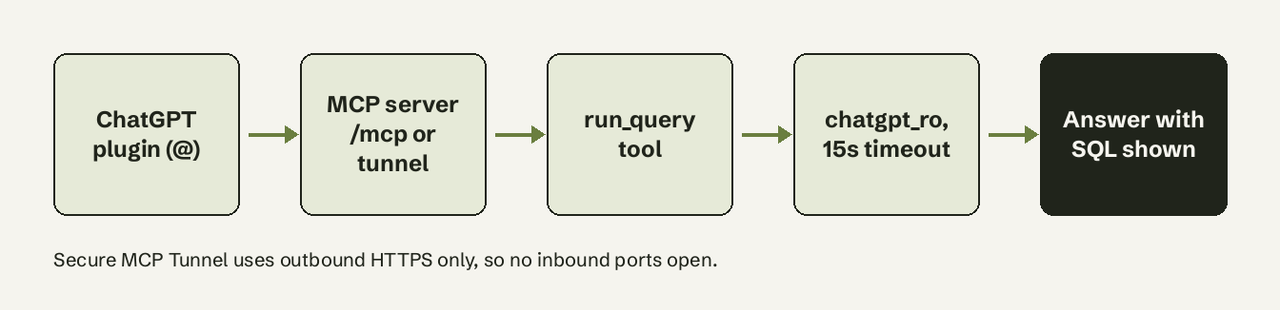
This is the route OpenAI now documents for bringing your own tools into ChatGPT. An MCP server exposes tools such as list_tables, describe_table and run_query; ChatGPT decides when to call them. Steps from OpenAI's connect and test guide:
- Pick or run a database MCP server. Use a maintained server for your engine (PostgreSQL, MySQL, SQL Server and SQLite all have them) or a hosted gateway. Point it at the read-only role from the prerequisites, never the owner account. Our [database MCP server guide](/blog/database-mcp-server-connect-claude/) compares the options.
- Make it reachable. Either serve it over public HTTPS with streamable HTTP at a path like
https://db-mcp.example.com/mcp, or keep it private with Secure MCP Tunnel: runtunnel-clientinside your network and it makes outbound HTTPS calls toapi.openai.com:443, so you open no inbound firewall ports. - Test the tools before ChatGPT sees them. Run
npx @modelcontextprotocol/inspector@latest, call each tool with normal inputs, an unknown table and an empty result, and confirm a write (DELETE FROM users) is refused. - Add it in ChatGPT. Go to chatgpt.com/plugins, select the plus button, then Add custom MCP server. Enter a name and description, choose the public URL (including
/mcp) or Tunnel, configure authentication (OAuth or a revocable key, never the database password), accept the risk warning, and select Create as a plugin. - Review the discovered tools. Check that only read tools are listed. If a server advertises write tools, fix the server, not the prompt.
- Use it. Start a new chat, type
@, pick the plugin, and ask: "Using the app database, how many paid signups did we get each week this quarter?" Ask ChatGPT to show the SQL it ran. - Refresh after changes. When tools or auth change, restart the server, open the connection in ChatGPT Plugins and select Refresh, then start a new conversation.
How to verify it worked: the answer should cite a tool call, the SQL should reference real tables, and the row count should match the same query run in psql. On PostgreSQL, SELECT usename, query FROM pg_stat_activity WHERE usename = 'chatgpt_ro'; shows the connector's queries while they run.
Common errors and fixes:
- ChatGPT cannot connect to the server: the URL is missing
/mcp, the server only speaks stdio, or TLS is invalid. Verify with MCP Inspector first. - `permission denied for table ...`: the table lives in a schema you didn't grant; grant that schema too.
- `canceling statement due to statement timeout`: the question scanned a big table; add a date filter or an index, don't raise the timeout to minutes.
- Tools look stale after an update: select Refresh and open a new chat.
ChatGPT for SQL Server, MySQL, PostgreSQL and data warehouses
The steps are identical across engines; only the MCP server and its driver differ. To connect ChatGPT to a data warehouse (BigQuery, Snowflake, Redshift), use a service account limited to viewer or read roles on the reporting datasets and set a bytes-scanned or warehouse-size cap, because one broad question can scan a whole table. If ChatGPT says it can't reach the database, it almost always means the server can't, not ChatGPT.
The Gap All These Approaches Share
None of these options give you, out of the box:
- Saved queries and dashboards that refresh automatically
- Scheduled reports delivered on a cadence
- Alerts that fire when something changes in your data
- Non-technical access that doesn't depend on someone's ChatGPT plan or a JSON config
- Shared definitions: two people asking "revenue" in ChatGPT can get two different SQL queries
ChatGPT is good at the "ask a question, get an answer" loop. It isn't built for the ongoing data work a team relies on every week.
What a Purpose-Built Tool Looks Like
If the real goal is "my team asks the database questions in plain English," AI for Database covers the parts ChatGPT leaves out. One person connects PostgreSQL, MySQL, SQL Server, MongoDB, Supabase, BigQuery and others with read-only credentials; everyone else asks questions in the browser and sees the SQL behind every answer. Answers can be pinned to dashboards that refresh on a schedule, and workflows watch a condition ("daily signups drop below 50") and send a Slack message, email or webhook. It's free to start with sample data, and Pro is $10 per user per month. Try AI for Database free at aifordatabase.com.
Which Approach Is Right for You?
| Scenario | Best approach | Setup effort | Who can use it |
|---|---|---|---|
| Quick SQL help for yourself | Paste schema into ChatGPT | Minutes | Anyone who can run SQL |
| Engineer wants live queries inside ChatGPT | Custom MCP server (Option 4) | An hour or two | People on a plan that allows custom servers |
| Prototype for a demo with fixed queries | Custom GPT + Action | A day | Anyone with the GPT link and plan |
| Building your own internal product | OpenAI API + your infrastructure | Weeks | Whoever you build it for |
| Whole team needs answers, dashboards, alerts | Purpose-built tool | Minutes | Non-technical teammates too |
For more side-by-side options, see [chat with your database tools compared](/blog/chat-with-your-database-best-tools-2026/) and [what comes after ChatGPT for database queries](/blog/beyond-chatgpt-database-queries-2026/).
The Bottom Line
Connecting a database to ChatGPT is useful and, with MCP, much easier than it was. Pasting schemas gets you SQL; a custom MCP server or GPT Action gets you live answers; the API gets you your own product. What none of them give a team is persistence: dashboards, schedules, alerts and shared definitions. Start with a read-only role whichever way you go.
Frequently Asked Questions
Can ChatGPT connect directly to a SQL database?
No. ChatGPT has no database driver. It connects through a tool you provide: a custom MCP server, a GPT Action calling your API, or a third-party app. That tool holds the credentials and runs the SQL.
How do I connect ChatGPT to SQL Server?
Create a SQL Server login in db_datareader for one database, run an MCP server that supports SQL Server against that login, expose it over HTTPS at /mcp or through Secure MCP Tunnel, then add it in ChatGPT under Plugins > Add custom MCP server.
How do I connect PostgreSQL or MySQL to ChatGPT?
Same steps: a read-only role (GRANT SELECT only), an MCP server for your engine, an HTTPS endpoint or tunnel, then Add custom MCP server. For a one-off query, pasting the CREATE TABLE statements and asking for SQL needs no connection at all.
Is it safe to connect ChatGPT to a production database?
It's safe enough when ChatGPT can only read: a dedicated read-only role, a statement timeout, a row cap, a revocable key instead of the database password, and logging of every query. Pointing it at the owner account is never safe; a model can be confidently wrong.
What database does ChatGPT use?
OpenAI doesn't publish ChatGPT's internal storage, and it doesn't matter for this task: ChatGPT reads your data only through the connector or Action you configure.
Do I need ChatGPT developer mode?
Only to add a custom MCP server yourself. Apps already listed in ChatGPT's directory install without it, and pasting schemas or using a Custom GPT doesn't need it.
Can ChatGPT query a data warehouse like BigQuery or Snowflake?
Yes, through an MCP server or Action that uses a read-only service account. Add a cost cap (BigQuery maximum bytes billed, a small Snowflake warehouse) because natural-language questions often scan more than expected. Our guide to [querying BigQuery without SQL](/blog/bigquery-without-sql-natural-language/) covers the warehouse side.
- HOW TO CONNECT YOUR POSTGRESQL DATABASE TO AN AI TOOL →
- HOW TO CONNECT YOUR DATABASE TO CHATGPT OR CLAUDE (2026) →
- CAN CHATGPT WRITE SQL QUERIES? WHAT IT GETS RIGHT AND WHERE IT BREAKS DOWN →
- 9 BEST QUERY BUILDERS FOR SQL: VISUAL, CODE, AI (COMPARED) →
- BEST TEXT-TO-SQL TOOLS IN 2026: 10 OPTIONS COMPARED →
- BEYOND CHATGPT: WHY PURPOSE-BUILT AI DATABASE TOOLS ARE BETTER IN 2026 →