
BigQuery SQL Syntax and Querying BigQuery Without SQL
TL;DR: BigQuery SQL is GoogleSQL, an ANSI-compliant dialect (formerly called Standard SQL) with BigQuery-specific syntax: backtick table names, DATE_ADD for dates, UNNEST for arrays, and a quantified LIKE ANY that many guides still say doesn't exist. If you don't write SQL, you can query BigQuery in plain English with Gemini in BigQuery, Looker or a natural language query tool that runs the SQL for you.
BigQuery uses GoogleSQL, which Google describes as ANSI-compliant and recommends for every new project; the older legacy SQL dialect still exists but Google recommends migrating away from it (BigQuery SQL dialects). So yes, BigQuery SQL is real SQL: SELECT, JOIN, GROUP BY and window functions work as you expect. What trips people up is the BigQuery syntax around it: table references, strict date types, pattern matching and cost. The cheat sheet below covers those, and the rest of this guide covers how non-technical teams query BigQuery without writing SQL at all.
BigQuery is one of the most powerful data warehouses available. It handles petabytes, scales automatically, and integrates with the rest of Google Cloud. It's also, for most non-technical users, inaccessible. The interface is a SQL editor. If you want to ask "which countries drove the most revenue last quarter?", you need to write something like:
SELECT
    c.country,
    ROUND(SUM(o.amount) / 1000000, 2) AS revenue_millions
FROM `project.dataset.orders` o
JOIN `project.dataset.customers` c ON o.customer_id = c.id
WHERE o.created_at BETWEEN '2025-10-01' AND '2025-12-31'
  AND o.status = 'completed'
GROUP BY c.country
ORDER BY revenue_millions DESC
LIMIT 20;
For a data engineer, that's straightforward. For a product manager or ops lead who just needs the answer, it's a wall between them and their own data.
BigQuery SQL syntax cheat sheet
This is the lookup table for the BigQuery syntax people search for most. Everything here is GoogleSQL, checked against the operators reference and string functions reference.
| Task | BigQuery syntax | Note |
|---|---|---|
| Reference a table | ` project.dataset.table ` | Backticks, three parts |
| Pattern match | name LIKE 'Ana%' | Case-sensitive |
| Match any of several patterns | name LIKE ANY ('Ana%', '%son') | SOME is a synonym |
| Match all patterns | name LIKE ALL ('%a%', '%n%') | Empty list returns TRUE |
| Exclude patterns | name NOT LIKE ANY ('test%', '%demo%') | Quantified NOT LIKE |
| Case-insensitive LIKE | LOWER(name) LIKE 'ana%' | No ILIKE operator |
| Substring | SUBSTR(sku, 1, 3) | SUBSTRING is an alias, 1-based |
| Contains text | CONTAINS_SUBSTR(title, 'blue') | Case-insensitive |
| Not equal | status != 'paid' or status <> 'paid' | Both work |
| Add a day | DATE_ADD(d, INTERVAL 1 DAY) | No d + 1 |
| Query an array | FROM t, UNNEST(t.tags) AS tag | Flattens repeated fields |
| Approximate distinct | APPROX_COUNT_DISTINCT(user_id) | Cheaper on huge tables |
Does BigQuery support LIKE ANY?
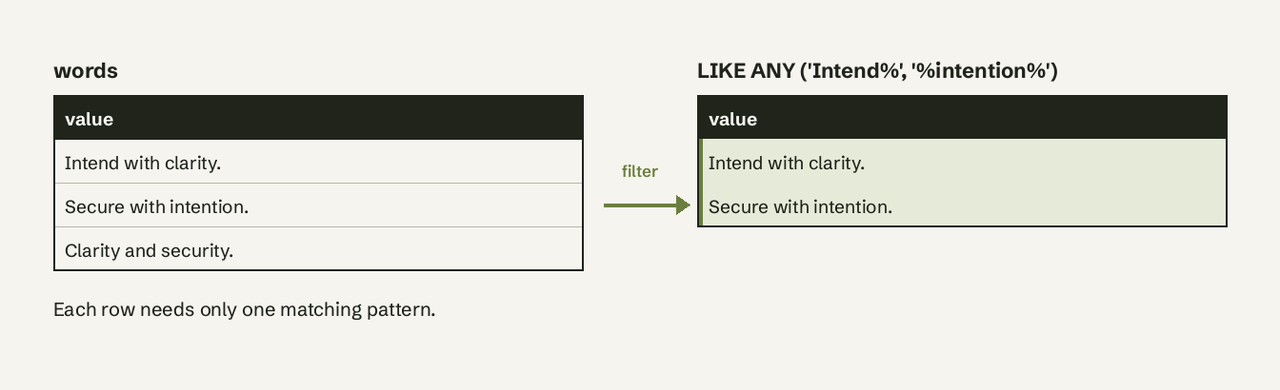
Yes. BigQuery supports the quantified LIKE operator: search_value [NOT] LIKE ANY|SOME|ALL (patterns), where the patterns are either a list or an UNNEST of an array. Several popular references, including the dbt SQL reference and Atlassian's BigQuery LIKE guide, still say BigQuery has no LIKE ANY and tell you to chain OR conditions; Google's current operators reference documents it with examples.
-- Rows whose value starts with 'Intend' or contains 'intention'
SELECT * FROM Words WHERE value LIKE ANY ('Intend%', '%intention%');

-- Patterns from an array, handy when the list comes from a parameter
SELECT * FROM Words WHERE value LIKE ANY UNNEST(['%ion%', '%and%']);

-- Every pattern must match
SELECT * FROM Words WHERE value LIKE ALL ('%ity%');
NULL rules matter in filters: NULL LIKE ANY ('a', 'b') returns NULL, an empty pattern list returns FALSE for ANY and TRUE for ALL.
How does BigQuery LIKE work?
BigQuery LIKE matches % to any number of characters and _ to exactly one character, and it is case-sensitive. Escape a literal % or _ with two backslashes ('\\%'), or one backslash in a raw string (r'\%'). For case-insensitive matching use LOWER() on both sides, or a case-insensitive collation such as COLLATE(name, 'und:ci').
SELECT email
FROM `myproject.crm.contacts`
WHERE LOWER(email) LIKE '%@acme.com'
  AND email NOT LIKE 'test\\_%';
Does BigQuery have ANSI SQL SUBSTRING?
Yes. BigQuery has SUBSTR(value, position[, length]) and accepts SUBSTRING as an alias, so ANSI-style code ports over. Positions are 1-based and a negative position counts from the end of the string.
SELECT
  SUBSTR(order_code, 1, 3)  AS region_prefix,
  SUBSTRING(order_code, -4) AS last_four
FROM `myproject.ecommerce.orders`;
Why BigQuery specifically presents a steeper curve
Most databases have similar SQL dialects. BigQuery's GoogleSQL is close to ANSI SQL, but it has its own quirks that trip up even experienced SQL writers:
- Table references use backtick syntax:
`project.dataset.tableinstead ofschema.table` - Date handling is strict: you can't add a day to a timestamp with
+ 1; you needDATE_ADD(date_col, INTERVAL 1 DAY) - Nested and repeated fields: BigQuery supports arrays and structs natively, which require
UNNEST()to query properly - Partitioned tables: querying without filtering on the partition column can scan terabytes and cost real money
-- Wrong: scans all partitions (expensive)
SELECT COUNT(*) FROM `myproject.analytics.events`
WHERE user_id = '12345';

-- Right: filters on partition column first (scans only relevant partitions)
SELECT COUNT(*) FROM `myproject.analytics.events`
WHERE event_date >= '2026-01-01'
  AND user_id = '12345';
These nuances mean that even if you know SQL from MySQL or PostgreSQL, BigQuery will catch you out. For non-technical teams the barrier is higher. If you're coming from Postgres, our SQL cheat sheet and the guide to filtering in SQL cover the shared basics.
What language does BigQuery use, and where does it sit among big data query languages?
BigQuery uses GoogleSQL, a SQL dialect, so it is a SQL database for analytics rather than a NoSQL store, even though it handles nested JSON-like records. Among big data query languages it sits with the SQL engines: Snowflake SQL, Amazon Redshift (PostgreSQL-derived), Spark SQL on Databricks, and Presto/Trino. HiveQL and Pig Latin were the Hadoop-era alternatives. The practical difference between them is dialect detail, such as BigQuery's quantified LIKE versus Snowflake's LIKE ANY, which both now exist, or BigQuery's lack of ILIKE.
Option 1: Looker Studio (Google's native option)
Google's official answer for non-technical BigQuery users is Looker Studio (formerly Data Studio). It connects to BigQuery and lets you build charts and tables through a graphical interface.
The trade-off: you're limited to the reports someone built in advance. Looker Studio is a good dashboard tool, but it doesn't let you ask new questions on the fly. If your dashboard shows revenue by country but you want revenue by acquisition channel, you either modify the dashboard or wait for someone to do it. For ad-hoc analysis, it doesn't solve the problem.
Option 2: Looker's LookML + Explore
If your company has full Looker (not just Looker Studio), Explore lets non-technical users build queries by clicking dimensions and measures. This is useful for the questions it supports.
The limitation: LookML models have to be built and maintained by a data team. If the metric you want isn't in the model, Explore can't answer it, and building LookML for a large schema is a significant project.
Option 3: Duet AI / Gemini in BigQuery
Google has added Gemini to BigQuery's query editor (it launched as Duet AI). You type a question in plain English and it suggests SQL, explains a query, or completes one. This helps SQL writers who want a starting point, and is less helpful for people who don't know SQL at all, because:
- It generates SQL in the editor, and you still review it and click Run
- Results come back as raw tabular data
- Suggestions can reference columns that don't exist when the schema context is thin
For a developer who wants to write SQL faster, it's useful. For a product manager who just wants an answer, it still requires SQL review.
Option 4: Natural language query tools with BigQuery integration
A different approach: tools built to take a plain-English question, generate SQL for your schema, run it, and return a formatted result. Read more on how text-to-SQL and natural language query systems work.
AI for Database works this way with BigQuery. You connect your BigQuery project with a read-only service account and ask questions like:
- "Show me the top 10 customers by total spend in the last 90 days"
- "What's our week-over-week user growth rate for the past 8 weeks?"
- "Which product categories have the highest return rate?"
It inspects your schema, generates BigQuery SQL (backtick names, partition filters, date functions), runs it, shows the SQL with the answer, and can pin the result to a self-refreshing dashboard or an alert. Try AI for Database free at aifordatabase.com; sample data is included.
Here's what the generated SQL for that last question might look like:
SELECT
    p.category,
    COUNT(DISTINCT r.order_id) AS returns,
    COUNT(DISTINCT o.id) AS total_orders,
    ROUND(COUNT(DISTINCT r.order_id) * 100.0 / COUNT(DISTINCT o.id), 1) AS return_rate_pct
FROM `myproject.ecommerce.orders` o
JOIN `myproject.ecommerce.order_items` oi ON o.id = oi.order_id
JOIN `myproject.ecommerce.products` p ON oi.product_id = p.id
LEFT JOIN `myproject.ecommerce.returns` r ON r.order_id = o.id
WHERE o.created_at >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 90 DAY)
GROUP BY p.category
ORDER BY return_rate_pct DESC;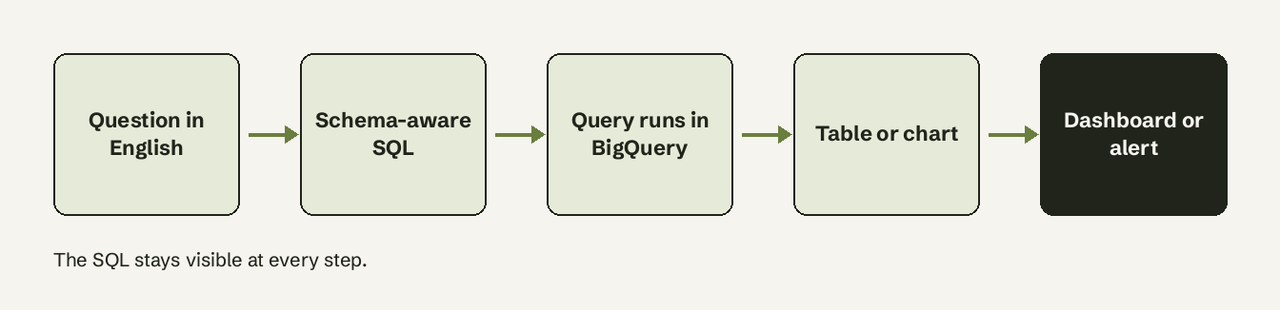
Connecting BigQuery to AI for Database
The connection takes about 10 minutes:
- Create a service account. In Google Cloud Console go to IAM & Admin, Service Accounts, Create Service Account. Name it something like
aifordatabase-reader. - Grant the right roles. For read-only access grant
BigQuery Data Viewer(read table data) andBigQuery Job User(run queries). - Download the key. Create a JSON key for the service account and download it.
- Connect. Select Google BigQuery as the database type, paste your project ID and the service account JSON. The schema is scanned automatically.
- Ask questions. You can start querying immediately.
What AI gets right (and where it still needs guidance)
Natural language to SQL has improved a lot, but it isn't perfect.
Where it works well:
- Aggregations: counts, sums, averages by dimension
- Time-based filtering and comparisons (last 30 days, year-over-year)
- JOINs between tables with obvious foreign keys
- Ranking and top-N queries
Where it needs context:
- Business definitions ("active users" = logged in within 30 days) the AI can't know
- Multi-step calculations such as cohort retention
- Ambiguous tables, such as both
usersandcustomers
The fix for ambiguity is to say what you mean: "Show me active users, defined as anyone with an event in the last 30 days." Generated SQL can still be wrong, which is why seeing it matters; see SQL hallucination.
BigQuery cost considerations
BigQuery's default on-demand model charges for bytes processed by each query, and the first 1 TiB processed per month is free (BigQuery pricing). Capacity pricing instead bills slots (virtual CPUs) over time. Under on-demand, a poorly written query that scans a 500 GB table costs real money, so tools that write BigQuery SQL should:
- Add partition filters when the table is partitioned
- Avoid
SELECT *on large tables, since BigQuery bills by columns read - Use approximate functions such as
APPROX_COUNT_DISTINCTwhere precision isn't critical
Check the bytes-processed estimate in the editor, or the generated SQL in your tool, before running anything large.
Building BigQuery dashboards without SQL
The same plain-English approach works for dashboards. Instead of writing SQL for every chart, describe each panel:
- "Bar chart: revenue by region, this quarter vs last quarter"
- "Line chart: daily active users, last 90 days, 7-day rolling average"
- "Table: top 20 customers by LTV, with plan type and signup date"
Set a refresh schedule and the dashboard refreshes automatically. Unlike Looker Studio, you're not limited to pre-built dimensions and measures.
Frequently Asked Questions
Is BigQuery SQL the same as standard SQL?
Mostly. GoogleSQL, previously named Standard SQL in BigQuery, is ANSI-compliant, so core syntax matches. Differences are in backtick table names, date functions, arrays with UNNEST, quantified LIKE and the absence of ILIKE.
Does BigQuery support LIKE ANY?
Yes. col LIKE ANY ('a%', '%b'), LIKE SOME and LIKE ALL are documented in Google's operators reference, including NOT LIKE ANY and array patterns with UNNEST.
Is there ILIKE in BigQuery?
No. Use LOWER(col) LIKE 'pattern', a case-insensitive collation, or CONTAINS_SUBSTR for a contains check.
Can I query BigQuery without knowing SQL?
Yes. Natural language query tools take plain-English questions, generate the BigQuery SQL, run it and return results. Gemini in BigQuery suggests SQL but you still review and run it.
Is it safe to connect AI tools to my BigQuery data?
Use a service account with minimum permissions, typically BigQuery Data Viewer and BigQuery Job User. That gives read-only access. Review the tool's data handling before connecting production data.
Will natural language queries work with partitioned BigQuery tables?
Good tools read partition keys from the schema and add partition filters, which matters for both cost and speed.
How is this different from Looker Studio?
Looker Studio shows reports someone built in advance. A natural language query tool answers new questions on the fly.
Is BigQuery a relational database?
BigQuery is a relational, SQL-based analytics data warehouse. It supports tables, joins and SQL, plus nested and repeated fields, but it is built for analytical scans rather than transactional workloads.